India Tech Hiring Trends 2025: What the Job Data Actually Shows
What 50,000+ Naukri job postings show about India tech hiring: which skills are surging and which cities are growing.
Pay-Per-Result vs Subscription Scraping: Why Billing Models Matter More Than You Think
Pay as you go, flat rate, per run or per result: what each scraper API billing model actually costs once runs start failing.
The Best Apify Actors for AI and LLM Projects in 2025
A curated list of Apify actors that ship data in formats LLMs can directly use, ranked by reliability, output quality, and billing fairness.
How to Aggregate Job Postings from 500+ Companies Using Public ATS APIs
Greenhouse, Lever and Ashby expose public job board APIs with no auth. Build one aggregator that pulls from all three, dedupes, and flags new roles.
Using Google Trends Data for Market Research: A Developer's Playbook
How to turn Google Trends data into market research you can act on, from keyword validation to seasonal demand forecasting.
Reddit Sentiment Analysis Pipeline: From Raw Posts to Actionable Insights
How to build a production sentiment analysis pipeline on Reddit data, from scraping and preprocessing to classification.
How to Build a RAG Pipeline Using Web-Scraped Content
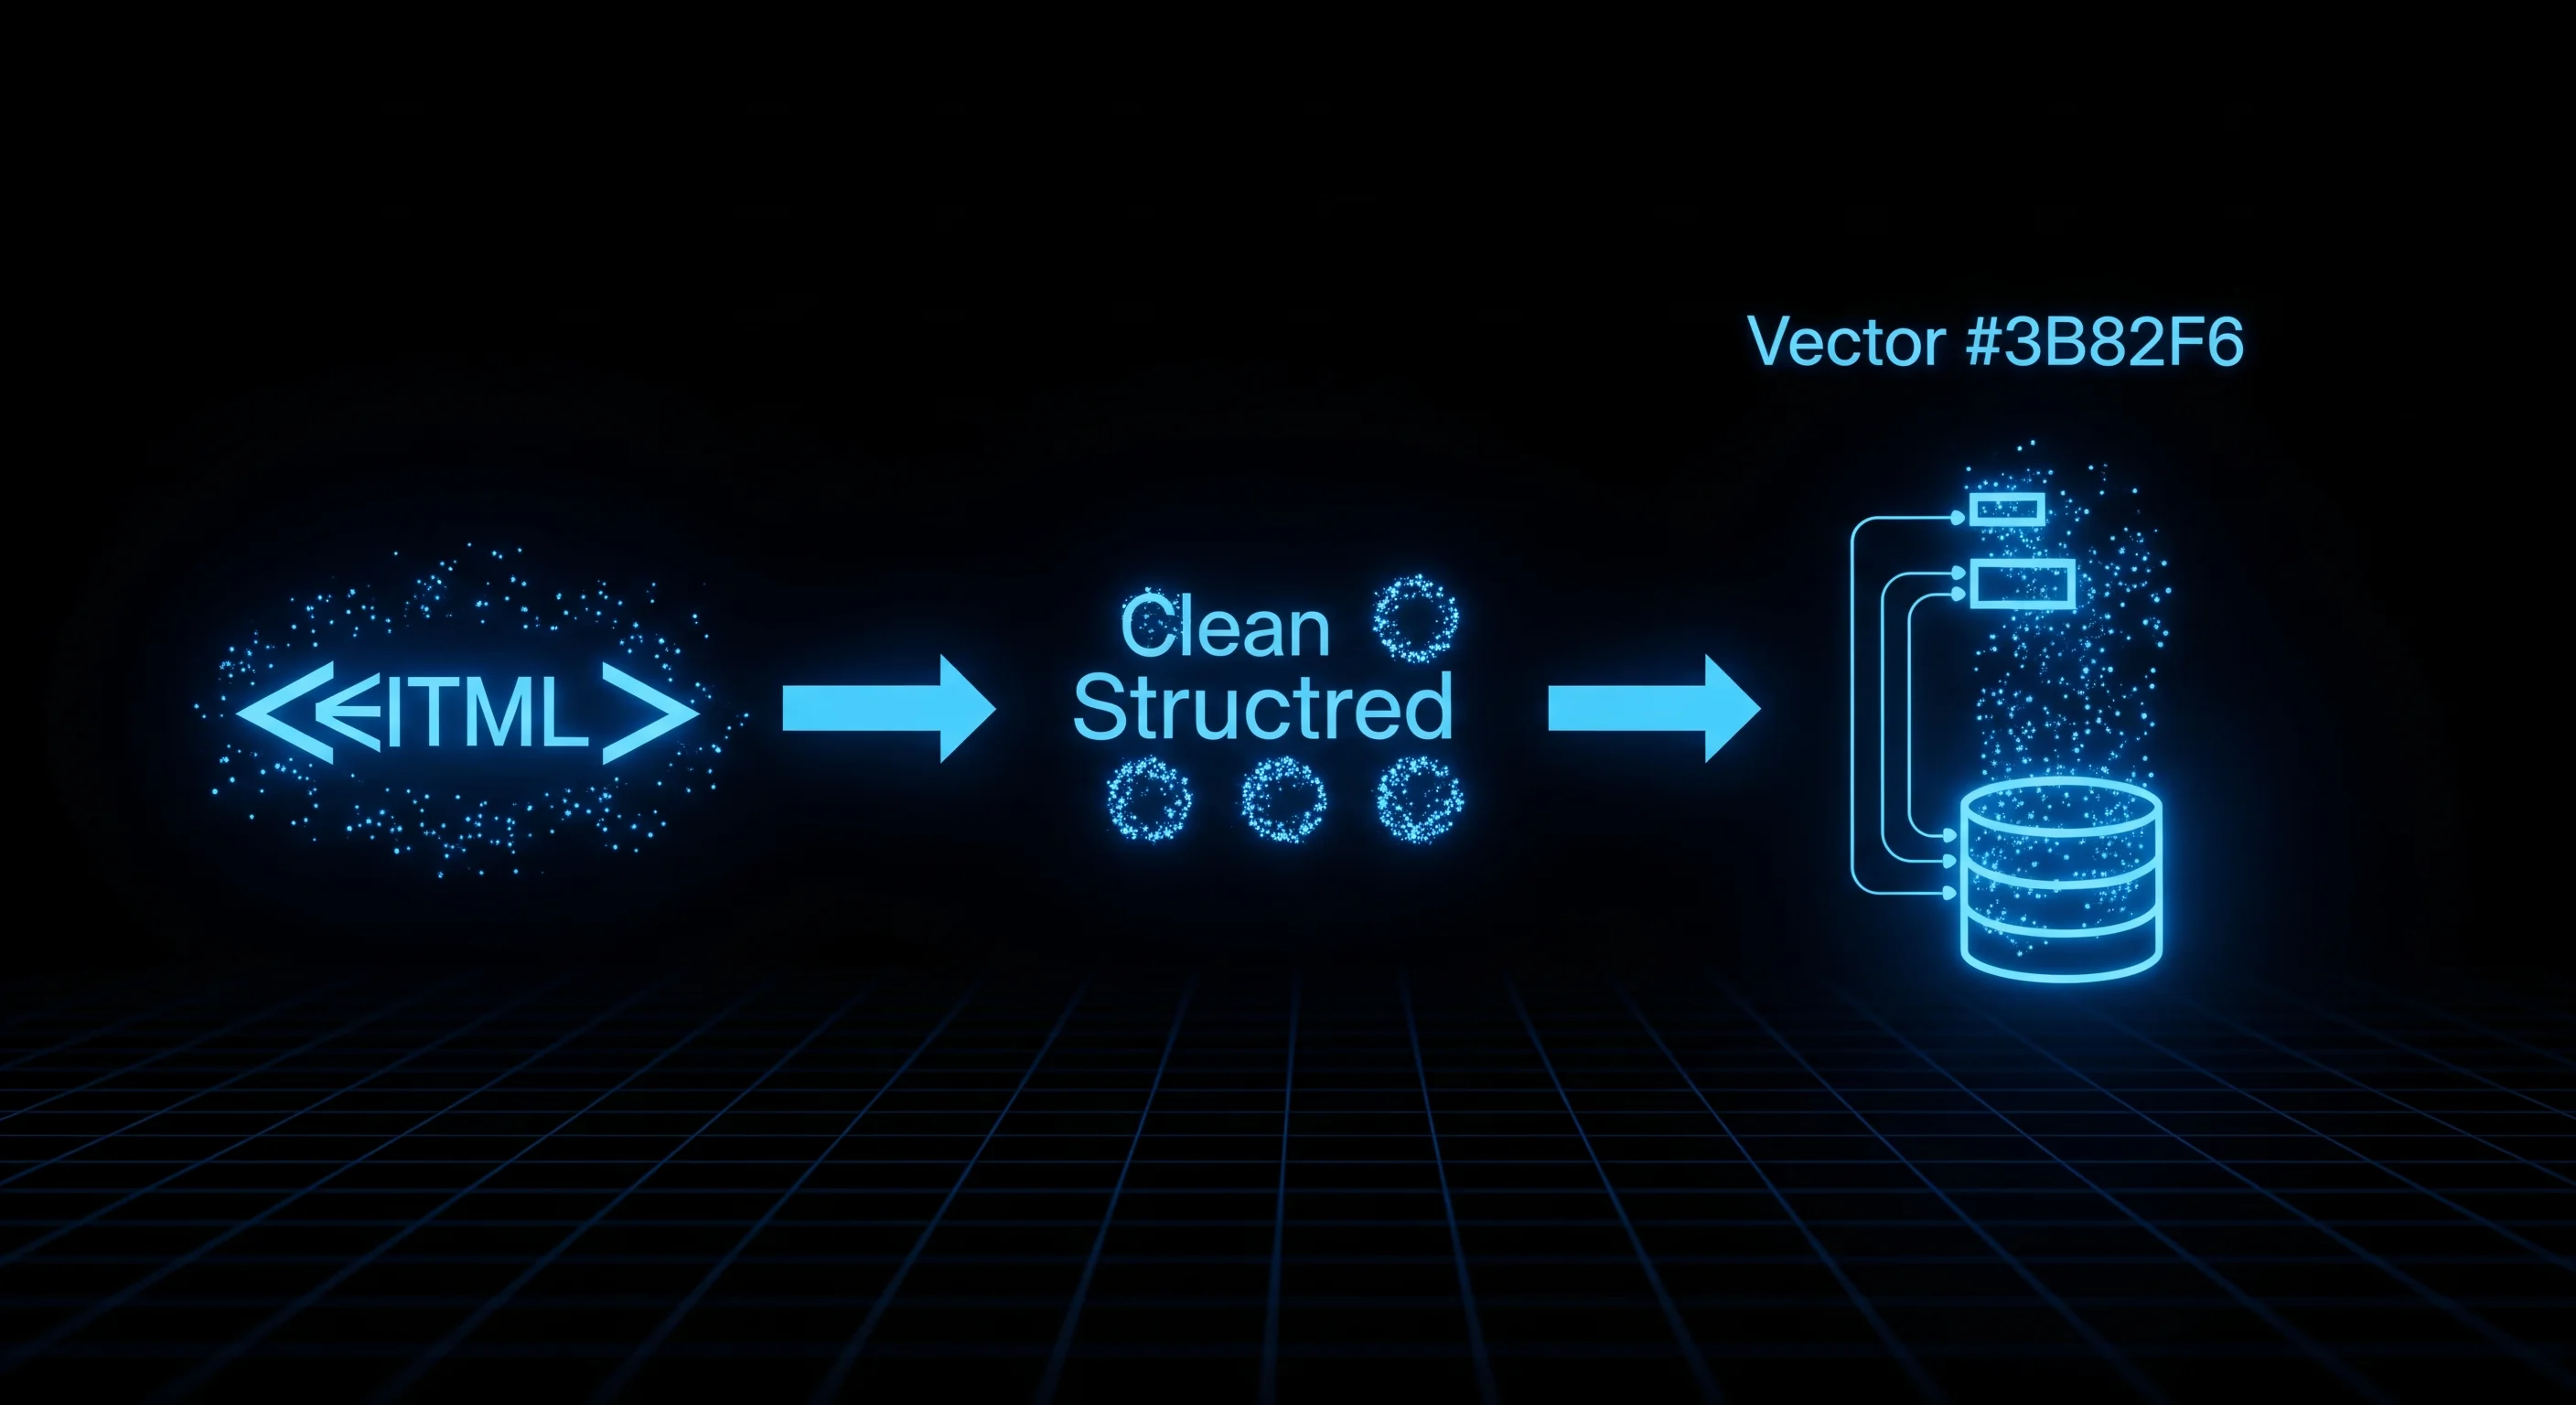
A complete guide to turning any website into LLM context, from crawling and chunking to embedding, retrieval, and keeping the index fresh.
Web Scraping Without Getting Blocked in 2025: Proxies, Stealth, and Session Strategy
A technical guide to getting past the five most common anti-bot systems: Cloudflare, Akamai, DataDome, PerimeterX and reCAPTCHA.
Apify vs Bright Data vs ScraperAPI vs Oxylabs: The 2025 Data Platform Comparison
We compared the four major web scraping platforms on pricing, ease of use, anti-bot capability, and proxy quality.
Greenhouse vs Lever vs Ashby: Which ATS Has the Best Public Job API?
Greenhouse, Lever, and Ashby all expose public job board APIs with no authentication. A field-by-field comparison of what each returns, their limits, and how to pull all three into one dataset.
Naukri API 2025: How to Programmatically Access India's Largest Job Board
Naukri has no public API. This guide covers the session-warming approach that gets past Akamai bot detection and returns structured job data.
How to Scrape Reddit Without an API Key in 2026
The old reddit.com .json endpoints now return 403 and commercial API access is enterprise-only. Every method that still works in 2026, with code you can use today.